A demonstration can extract a clean table and still tell you very little about whether the same workflow will survive your document archive. Supplier layouts vary, scans are incomplete and a field may carry a different meaning in another document family. The important question is not whether a model can produce structured output. It is whether the resulting records are reliable enough for a clearly defined use.
Evaluation should therefore begin with the receiving process. A descriptive classification used for browsing has different consequences from a technical value copied into a quality workflow. Treating both as one generic accuracy problem hides the tradeoff that the business owner actually needs to make: which errors are tolerable, which require review and which should stop the record from being used.
Step 1
Define fields and their consequences
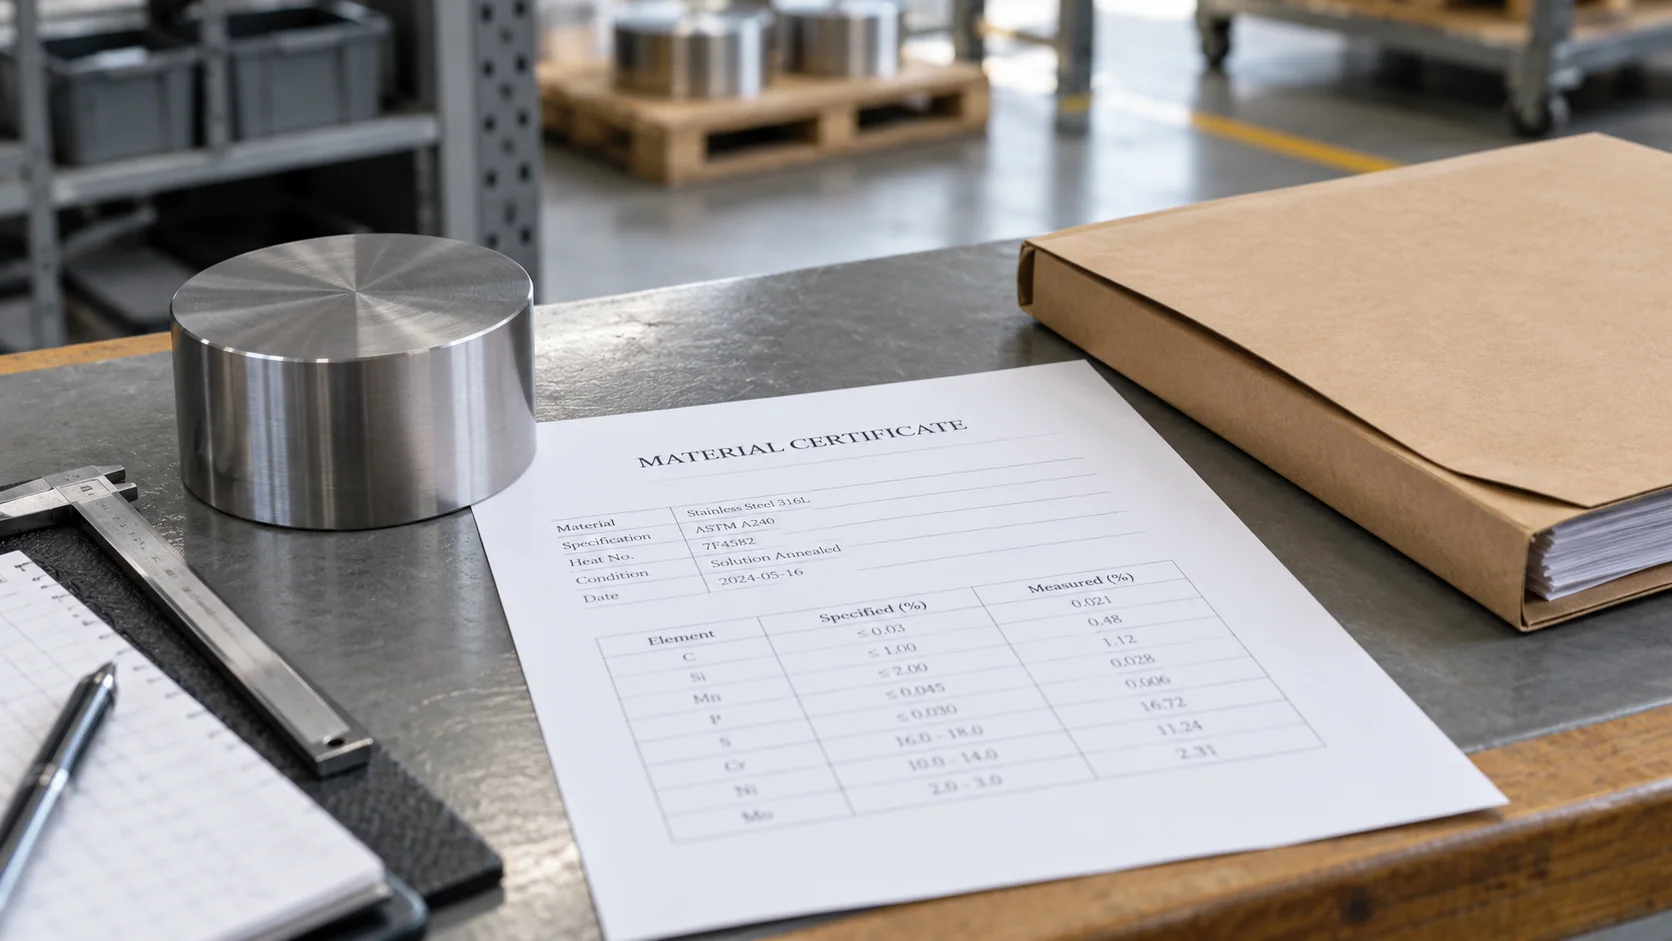
Write a short specification for every field before choosing an extraction method. Include the meaning, allowed format, units, source location and what happens when the value is missing or ambiguous. Distinguish a field that was not present from a field the pipeline failed to read. Otherwise a blank output can conceal two entirely different conditions, and downstream users will have no reliable way to interpret it.
Ask the receiving team to classify fields by the decisions they influence. A part identifier may need an exact match, while a summary requires a different review method. Define how multiple candidates, conflicting documents and superseded revisions should be handled. Establish the review rule in advance. A model's confidence score is not a substitute for an acceptance criterion that the process owner understands and can defend.
Step 2
Use representative documents and an independent reference
Select documents across the layouts, suppliers, languages and scan qualities that the intended workflow must handle. Include difficult and incomplete examples, not just the files used during configuration. Have qualified reviewers establish the reference values and record disagreements. The reference itself can be wrong, so corrections need their own review history. Keep a separate set for final evaluation so repeated tuning does not turn the test into a rehearsal.
Measure errors at the field level and inspect their distribution. Missing values, wrong values and values attached to the wrong entity should be counted separately. Check whether the cited page or region actually contains the evidence. The NIST AI Risk Management Framework offers general guidance for managing and measuring AI risks; the concrete thresholds still need to come from the use case and the consequences of an error.
Step 3
Evaluate the entire review workflow
An extraction result is only one part of the delivery. A reviewer needs the original document, the proposed value, the relevant source location and a clear way to accept or correct the record. Test whether a person can resolve an exception without reopening several unrelated systems. Record the time and expertise required to review difficult cases. A pipeline that appears accurate but creates an unmanageable review queue may not fit the operation.
Repeat the agreed evaluation when layouts, models or extraction rules change. Version the configuration and preserve enough evidence to investigate a regression. Define what happens when an unfamiliar document arrives: route it for review or mark unsupported content clearly. Do not silently reuse a familiar schema when its assumptions no longer hold. Production readiness includes ownership of exceptions and a way to stop unreliable records from reaching downstream consumers.
How sDEN approaches it
Connected knowledge. Inspectable evidence.
Apply these principles to a defined collection and a practical decision.
Within this scope
Start with the customer's information needs
sDEN Solutions identifies the fields that matter and extracts them into a defined structure. The target schema is shaped by the customer's workflow rather than by a generic demonstration.
Within this scope
Choose methods by content
OCR, private models and deterministic methods are selected for the document and task. Structured output remains connected to the source, so reviewers can inspect what produced a value.
Within this scope
Apply review where accuracy matters
Human review can be used for critical fields and ambiguous cases. Verified records can then be delivered into existing applications, analytics and AI tools with their evidence attached.
A useful first delivery
What your team should be able to use
The useful deliverable is an acceptance report tied to a real workflow: which document families are supported, how each important field performs, which exceptions need review and who owns the process. Keep the evaluation set and reference records available for future changes. That gives the organization a repeatable basis for deciding whether the extraction service is ready, rather than a memorable demonstration with no durable comparison.
Questions
Manufacturing knowledge, answered.
What accuracy target should we choose?
There is no universal target. Set thresholds by field and consequence, including the cost of reviewing exceptions. Critical values may need explicit verification even when aggregate extraction performance looks strong.
Can human review compensate for every error?
Only if the workflow exposes uncertainty and reviewers have enough time, context and authority. Review is a designed operational step, not a guarantee that any volume of inaccurate output can be made safe.
Sources